 IEEE/ICACT20250013 Slide.12
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20250013 Slide.12
[Big Slide]
| Oral Presentation |
|
|
|
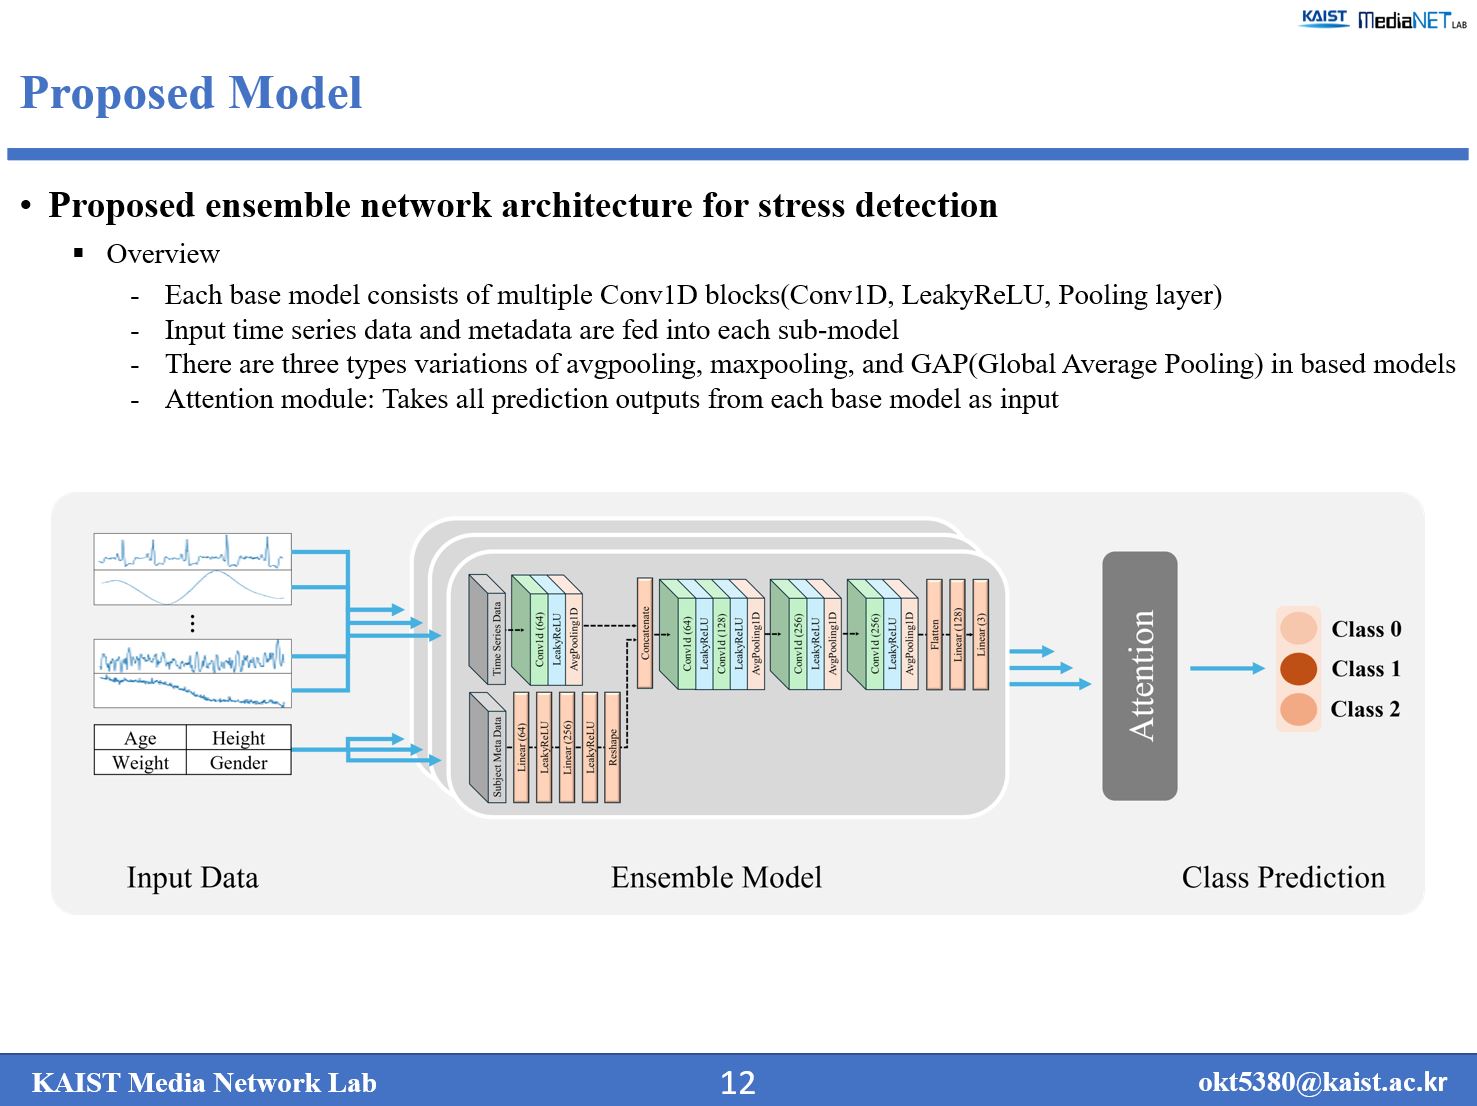
Here we have our proposed ensemble network architecture. Each base model is composed of multiple Conv1D blocks, and time-series data along with metadata are fed into each sub-model. We used three types of pooling layers: average pooling, max pooling, and global average pooling (GAP). Finally, the prediction values from each sub-model are passed to an attention layer that generates the final prediction. | |
| [Go to Next Slide] |