 IEEE/ICACT20250013 Slide.13
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20250013 Slide.13
[Big Slide]
| Oral Presentation |
|
|
|
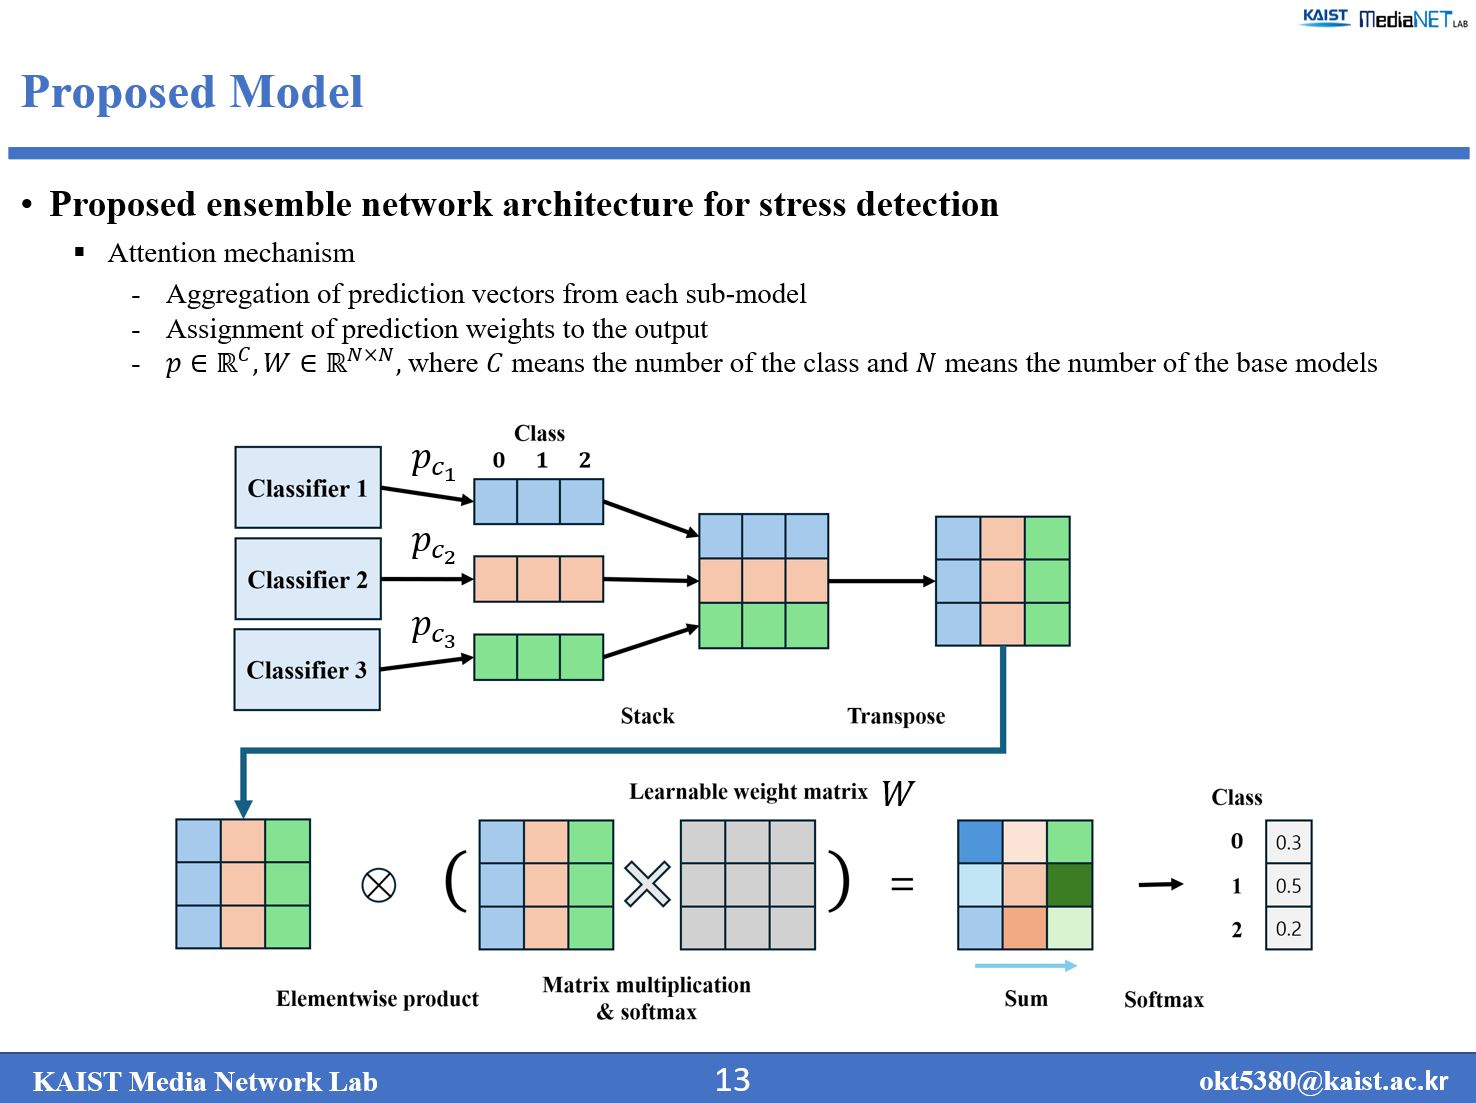
The attention module stacks all sub-results, transposes them, and multiplies them by a learnable weight matrix. It then sums these values over the dimension corresponding to the number of submodels. | |
| [Go to Next Slide] |